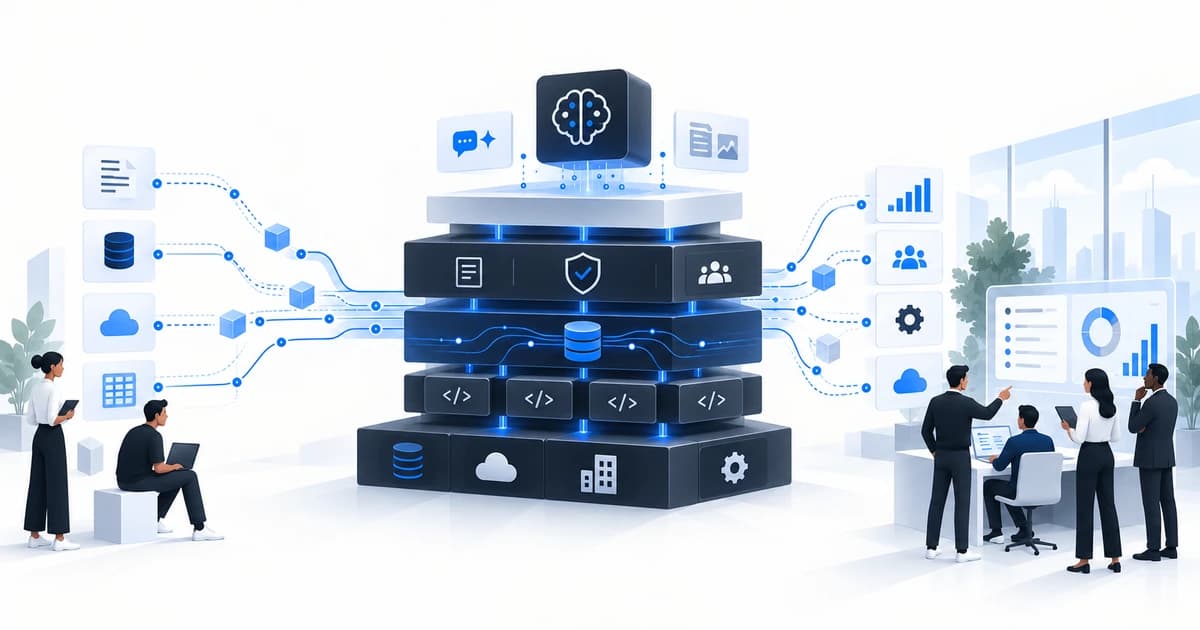
The visible part of an AI product is usually the model. The durable part is everything underneath it.
When an AI prototype fails, teams often blame model quality. In enterprise environments, the deeper cause is frequently architecture: the system cannot reliably identify users, retrieve current data, execute business actions, enforce permissions, or explain what happened after an automated decision.
This is why AI-ready architecture begins below the model layer.
1. APIs turn AI from text generation into action
A language model can explain what should happen. An enterprise system needs to know whether it is allowed to make it happen.
Useful AI products therefore need stable interfaces for actions such as:
- create or update a customer;
- check inventory;
- retrieve a policy;
- create a task;
- request approval;
- issue a draft quotation;
- reconcile a payment;
- escalate an exception.
Without APIs or service boundaries, teams end up automating brittle browser interactions or giving models direct access to internal data structures. Both approaches become hard to govern at scale.
2. Data needs semantics, not only availability
Giving an AI system access to “all company data” is not a strategy. The system needs to understand which records are current, who owns them, what they mean, and what happens when information conflicts.
A robust data layer defines:
- canonical identifiers;
- source-of-truth systems;
- freshness expectations;
- tenant and organization boundaries;
- audit timestamps;
- explicit null/unknown states;
- retention rules where applicable.
For AI, truth-state design is especially important. Zero, empty, unknown and error are not interchangeable. If a query fails and the application interprets that as “no records,” an AI agent may make a confident decision from missing evidence.
3. Identity becomes infrastructure for both humans and machines
As AI systems gain tools, they begin to act more like users. That creates a new identity problem: what is the agent allowed to do, on whose behalf, for how long, and with which context?
Gartner's 2026 security research emphasizes identity as foundational infrastructure as machine identities and autonomous workloads grow. For product teams, the practical takeaway is to avoid a single all-powerful AI credential.
Prefer scoped permissions, short-lived credentials where possible, explicit user or system context, and complete logs of sensitive actions.
4. Observability must include business behavior
Traditional application monitoring asks whether services are up. AI products need another layer: are they making useful, permitted and economically sensible decisions?
Useful telemetry includes:
- tool calls and outcomes;
- human approvals/rejections;
- retrieval sources;
- model/version changes;
- failure classes;
- cost per workflow;
- fallback rate;
- user correction rate.
This allows teams to improve not just technical reliability but operational quality.
5. Architecture should separate experimentation from authority
Companies need room to experiment quickly without allowing experimental AI to affect production truth.
A healthy architecture separates:
- sandbox vs production tools;
- read vs write capability;
- low-risk vs high-risk actions;
- recommendation vs execution;
- reversible vs irreversible actions.
This gives teams more freedom to innovate because risk boundaries are explicit.
6. The model should be replaceable
The AI model market changes quickly. Architecture that ties business logic directly to one model provider creates unnecessary lock-in.
The goal is not complete abstraction for its own sake. It is to keep domain logic, permissions, workflow state and business rules outside the model so the organization can change models without rewriting the business.
Gartner's 2026 software engineering guidance similarly emphasizes AI-ready APIs, data and secure engineering foundations as prerequisites for scaling AI value.
A simple readiness test
Before launching another enterprise AI feature, ask:
- Can the system reliably identify the user or agent?
- Is data current, scoped and attributable?
- Are business actions exposed through controlled interfaces?
- Can high-risk actions require approval?
- Can we reconstruct what happened afterward?
- Can a failed query be distinguished from an empty result?
- Can we change the model without changing core business rules?
If several answers are “no,” model selection is probably not the most important problem yet.
NAIT's product engineering approach treats AI as a layer in a larger software system. The goal is an architecture where intelligence can scale because data, actions and controls are trustworthy enough to support it.